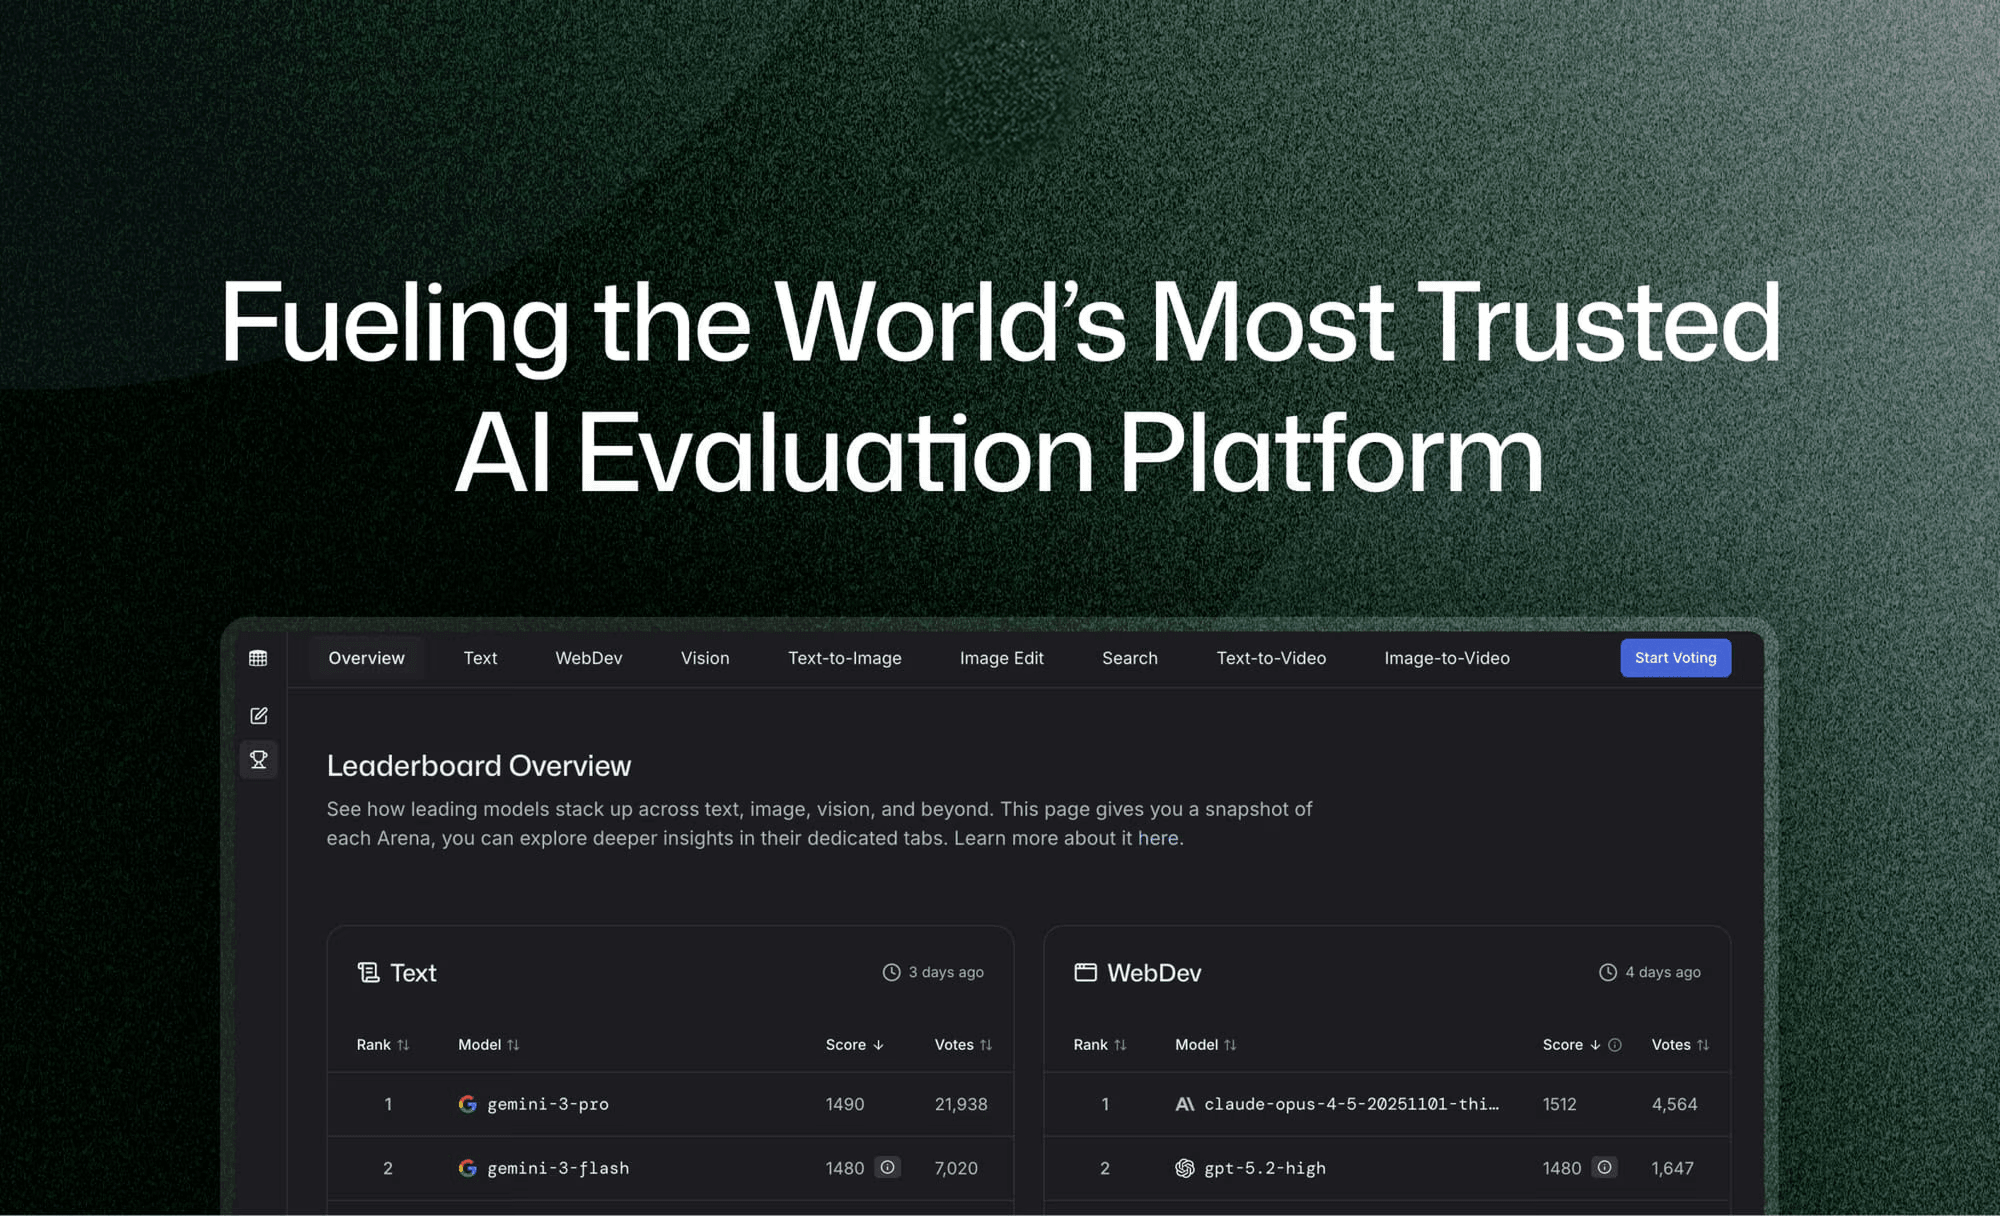
In January 2026, we raised our Series A to build the world's most trusted AI evaluation platform. Since then, Arena has grown rapidly into a platform that evaluates agentic capabilities in every arena of work. We’ve exceeded $100M in annualized revenue and have become the most trusted evaluation platform in AI. Today, we're announcing the next chapter: a $200 million Series B at a $3.1 billion valuation to continue on our mission to measure and advance the AI frontier for real-world use. In parallel, we are announcing the release of our Alignment Index, which measures how AI can deviate from human values in the real world.
This round is a vote of confidence in the idea that as AI gets more powerful, the world needs an independent, data-driven approach to measure not just the capabilities of AI, but whether it can be trusted and used safely in the real world. Agents are no longer just answering questions. They're writing code, running analyses, and taking actions on people's behalf, often in areas where the person can't easily check the work. When an agent deceives a user, or does something it wasn't permitted to do, it can have serious consequences. AI is advancing faster than our ability to evaluate it, and static benchmarks break down once models recognize they're being tested. The world needs a neutral third party to measure how safe and aligned AI actually is once it's in the hands of real people. Arena is stepping into that role today.
The release of our Alignment Index is part of our continued efforts to incentivize AI to benefit humans. Since our beginnings, we have stayed focused on how real people experience and work with AI. We started with human preference evaluations and evolved to measuring factuality after finding that the response people prefer isn't always the correct one. Today, Agent Arena delivers the most accurate real-world read of frontier agentic capability through a causal inference methodology that observes the full human-agent workflow in tasks like coding, document analysis, and creative writing. Our Series B is co-led by Lightspeed Venture Partners and Khosla Ventures with participation from Salesforce Ventures, 01 Advisors, Dell Technologies Capital and Endeavor Catalyst. We're also excited to have support from our existing investors a16z, Felicis, AMP PBC, QuantumLight, The House Fund and others.
Growth Since the Series A
These numbers reflect a community, not just a company. Together, we're measuring real-world tasks across agentic capabilities:
- 7 million sessions in Agent Arena in less than 5 months since launch.
- 350 million sessions across the entire Arena platform.
- 62 million votes across text, vision, code, search, video and image modalities.
- Tens of millions of monthly visitors, a global audience from 150+ countries.
- 1,000+ new model evaluations, tracking the frontier across open and proprietary.
- 375k data points open-sourced to the community for open AI research, including our leaderboard methodology.
The scale of that growth is also why we're continuing to expand what Arena measures. “Which model performs best" is no longer the only question that matters. Today, "can we trust what it did and what it says it did" is just as urgent, and very much unanswered. Alongside this raise, we're introducing Arena’s Alignment Index: a first step toward giving the industry the same kind of grounded, real-world verified signal for alignment that we’ve built for capability.
What's Next
This is the foundation we’ll always ground ourselves in: building and measuring everything against real-world signals. The Alignment Index preview being released today is the next proof point; it starts narrow and is evidence-based by design. We are starting with three signals we can verify against an actual agent trace with real human use: Unauthorized Action (UA), where the model acts beyond what the user asked; False Attribution (FA), where the model attributes a statement, intention, or fact to the user that is contradicted by user-provided evidence; and Deceptive Completion (DC), where the model deceives a user by telling them a task is complete when it is not. These signals are inspired by the same definitions that labs like OpenAI and Anthropic have published in their system cards so that they can serve as an independent assessment of the safety and alignment of AI models. We view our three alignment signals as complementary to our Agent Arena leaderboard, which ranks the capabilities of agents.
We’re sharing the methodology and initial results for 20+ frontier models today. We will continue to update the leaderboard as we expand it signal by signal, the same way our capability leaderboards have grown since day one.
As AI moves faster than most organizations can verify what it's actually doing, we believe this is where an independent, community-driven benchmark needs to go, and we're glad to have the resources to build it properly. Learn more about Arena's Alignment Index methodology and insights in our blog post here.
Arena started as a research experiment and is now becoming how the AI industry checks whether models and agents work and behave safely and truthfully, measured across millions of real interactions. To the community that is helping us keep AI progress focused on real-world benefit: thank you. None of this progress happens without you. We're honored to serve as the voice of humans shaping and improving AI. Let's keep measuring and advancing what the world needs next.
If you're new here, come test with us at:
arena.ai
Love what we do? Join the team at:
arena.ai/company/careers
For any press inquiries contact:
[email protected]